

Text recognition (OCR)
Text recognition returns the lines of text found in an image, each with its text, a confidence, a bounding box, a four-corner quadrilateral and, by default, word-level boxes. One call handles one image, whatever the number of lines. Typical uses are screenshots, UI captures, receipts, code windows, cropped regions and any case where the text is to be copied out as it is. To get the layout of a document page (reading order, tables, formulas), see Document parsing.
Line recognition
Section titled “Line recognition”Every text line found in the image is returned as an entry of lines, with the recognised text, a confidence, an axis-aligned bbox and a four-corner quad that fits tilted text more closely than the box does. Lines below options.minConfidence (default 0.5) are dropped.
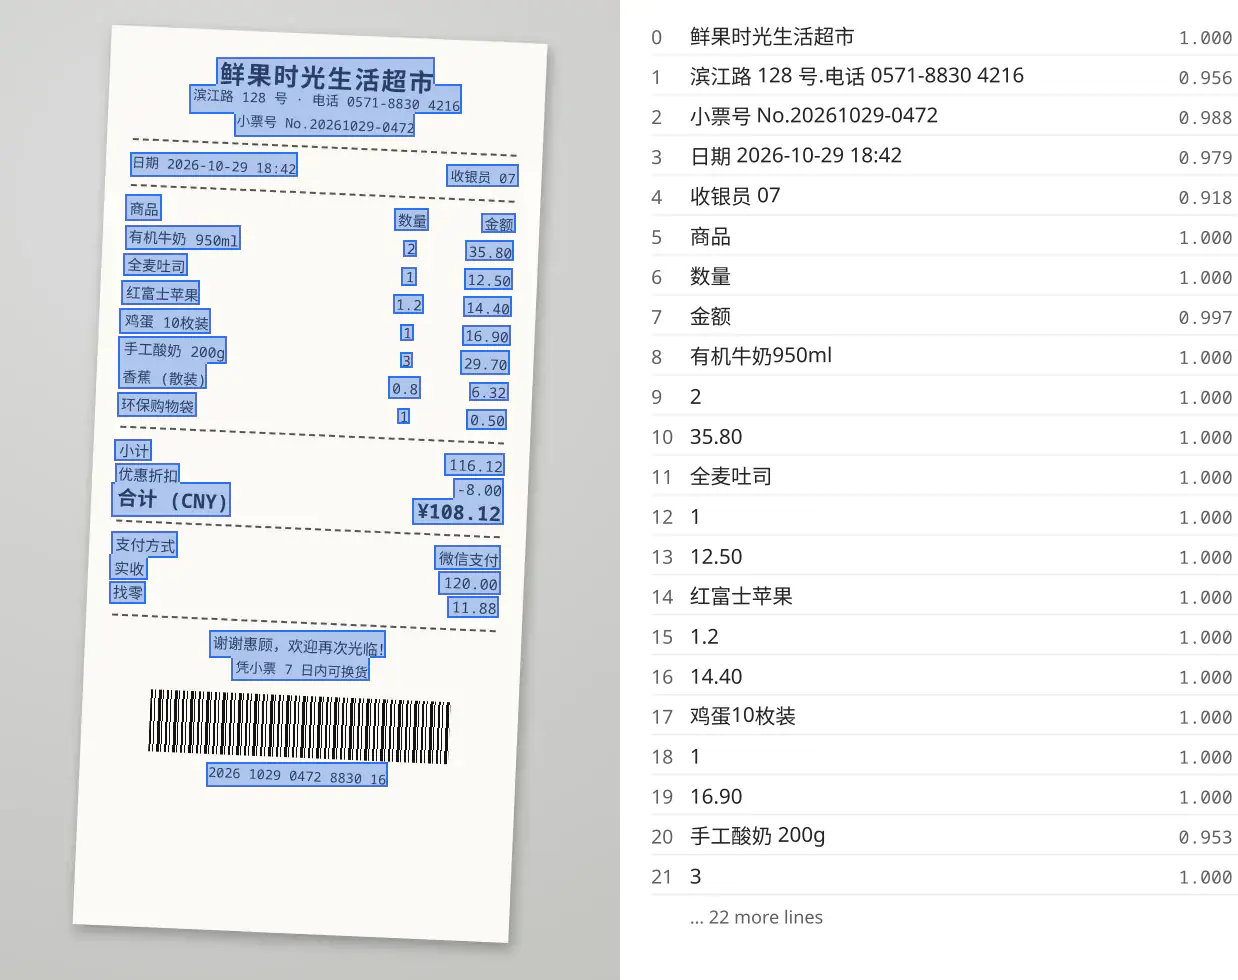
ppocr-v6: recorded Playground result for a photographed, slightly rotated receipt. Each box is one entry of lines; the list on the right shows text and confidence, with the first 22 of 44 lines.
Word boxes
Section titled “Word boxes”With options.words (default true), every line carries words: the pieces of the line with their own text, confidence, bbox and quad. Word boxes locate a single token inside a line, for example to highlight a search hit or to place a click target. Whitespace can appear as a word of its own. With options.words set to false, words is omitted and the response is smaller.
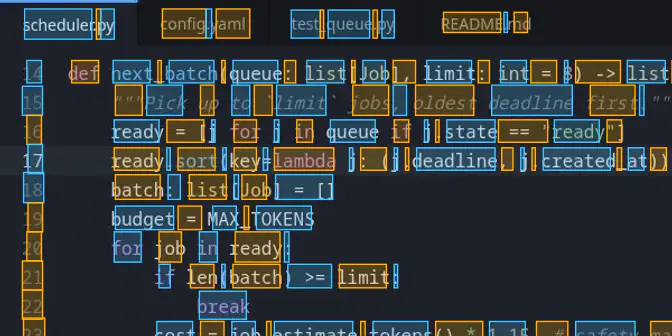
ppocr-v6: recorded Playground result for an editor screenshot. Each box is one entry of lines[].words; the two colours alternate only to tell neighbouring words apart.
Supported models
Section titled “Supported models”ppocr-v6 is the default and only model of POST /v1/ocr.
Plain lines come from ppocr-v6. paddleocr-vl also reads any page image, but it is a document parser billed per page and is called through POST /v1/documents/parse; the table compares the two for reading text.
ppocr-v6 |
paddleocr-vl |
|
|---|---|---|
| Model | PP-OCRv6 small | PaddleOCR-VL 1.6 (0.9B) with PP-DocLayoutV3 layout analysis |
| Endpoint | POST /v1/ocr |
POST /v1/documents/parse |
| Accepts | One image: screenshot, crop, photo | One page image |
| Returns | Lines of text with confidence, boxes, quadrilaterals and word boxes | Layout blocks in reading order, tables as HTML, formulas as LaTeX, the page as Markdown |
| List price (credits) | 0.25 per image | 2 per page |
| Pool | Public: available to every registered account, 100 calls per UTC day included | Paid: billed from the balance |
| Recorded processing time | 753 ms (one recorded call) | 1294 ms (one recorded call) |
| Pick when | The text is to be copied out as it is | Layout, reading order, tables or formulas are needed |
- Pick
ppocr-v6for screenshots, UI captures, receipts, code windows and cropped regions, and whenever the lowest cost matters. Grouping lines into paragraphs or columns is left to the caller. - Pick
paddleocr-vlfor invoices, papers, reports and book pages, where blocks, reading order, tables and formulas are needed. See Document parsing.
Example call
Section titled “Example call”One screenshot of an account settings page, sent to POST /v1/ocr with the default options:
curl https://api.stack.foldbun.com/v1/ocr \ -H "Authorization: Bearer $FOLDBUN_API_KEY" \ -H "Content-Type: application/json" \ -d '{ "model": "ppocr-v6", "image": { "id": "img_2dedd0716bfd46ec29b286a279d18b6fc80631e5d90fedb5c63eb36f231622e6" }, "options": { "minConfidence": 0.5 } }'The response is abridged: one of the recognised lines is shown.
{ "id": "call_01a1913d-55cd-7bee-ba86-bbbef2aa9bae", "model": "ppocr-v6", "image": { "id": "img_2dedd0716bfd46ec29b286a279d18b6fc80631e5d90fedb5c63eb36f231622e6", "width": 1100, "height": 760, "bytes": 83478, "contentType": "image/jpeg" }, "lines": [ { "text": "Sign out", "confidence": 0.9786, "bbox": [982, 32, 1053, 56], "quad": [[982, 32], [1053, 32], [1053, 56], [982, 56]], "words": [ { "text": "Sign", "confidence": 0.9786, "bbox": [990, 32, 1018, 56], "quad": [[990, 32], [1018, 32], [1018, 56], [990, 56]] }, { "text": " ", "confidence": 0.9786, "bbox": [1018, 32, 1022, 56], "quad": [[1018, 32], [1022, 32], [1022, 56], [1018, 56]] }, { "text": "out", "confidence": 0.9786, "bbox": [1026, 32, 1050, 56], "quad": [[1026, 32], [1050, 32], [1050, 56], [1026, 56]] } ] } ], "cost": 0.25, "balance": 12.5, "timing": { "queueMs": 0, "processingMs": 753 }, "billing": { "lines": [ { "unit": "image", "quantity": 1, "unitPrice": 0.25, "amount": 0.25, "waived": false } ], "total": 0.25, "charged": true, "pool": null }}Reading the response
Section titled “Reading the response”linesholds the recognised lines, sorted top to bottom and then left to right. The model does no layout analysis: reading order and paragraphs are left to the caller. Each line hastext,confidence(0.9786 here),bboxandquad.bboxis[x1, y1, x2, y2]andquadholds the four corners of the line, both in pixels of the oriented original, 1100 × 760 here (image.width,image.height). The order of the corners is described in the API reference.wordssplits the line into pieces with their owntext,confidence,bboxandquad: hereSign, a space andout, because whitespace can appear as a word of its own. Withoptions.wordsset tofalse,wordsis omitted.billing.chargedistrueandpoolisnull: the call was debited from the balance, socostis 0.25.
All fields: API reference.
Cost of this call. 0.25 (image) credits per call, whatever the number of lines or words, as charged in this response. Calls inside the public pool’s daily allowance are not charged. Unit prices: Billing.
Endpoints and reference
Section titled “Endpoints and reference”| Endpoint | In this use case | Reference |
|---|---|---|
POST /v1/ocr |
Lines of text with confidence, boxes and quadrilaterals, and by default word boxes, from one image | API reference |
POST /v1/documents/parse |
Structure (blocks, tables, formulas) instead of plain lines | API reference |
ppocr-v6andpaddleocr-vl: how each model works, its limits and measured latency.- Billing: the unit of each model;
ppocr-v6bills oneimageper call. - Document parsing: blocks, reading order, tables and formulas of a page.
- Images: the pixel space of boxes and quadrilaterals.