

Concept segmentation
Concept segmentation returns a mask for every instance of a concept: all the cars in a street scene, all the plums on a stall, every object that looks like a boxed example. The number of instances is not known in advance, and the caller marks none of them. Typical uses are counting, auto-labelling datasets and finding all objects of a kind before filtering them. To segment objects that the caller marks with a point, a box or clicks, see Interactive segmentation.
Text prompts
Section titled “Text prompts”A text prompt names a concept in 1 to 200 characters. Every instance of the concept in the image is returned as its own mask, with a score. Several prompts can share one call, and the image is encoded once for all of them (see How SAM calls are billed).
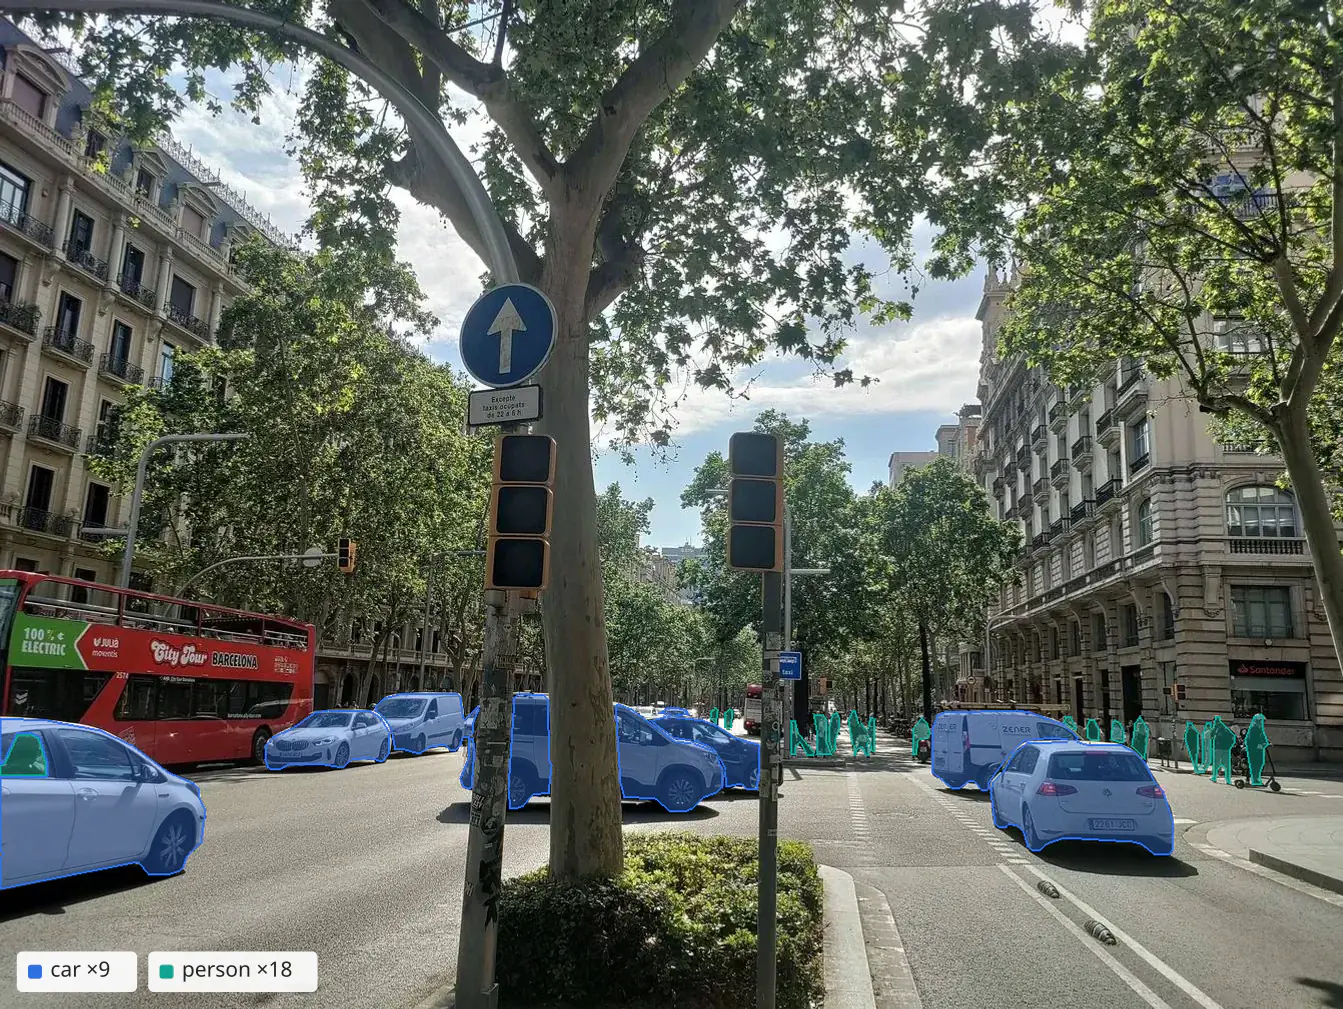
sam3: recorded Playground result for the prompts car and person. Each mask is one entry of instances, coloured by prompt.
Exemplar boxes
Section titled “Exemplar boxes”An exemplar box is [x1, y1, x2, y2] around one object. With boxes only, sam3 returns the boxed object and the objects that look like it: all boxes of the call together form one visual query. Boxes and text prompts can be mixed; the boxes then condition every text prompt of the call. Exemplar boxes suit things that are hard to name or that have many look-alikes, such as the fruit below.
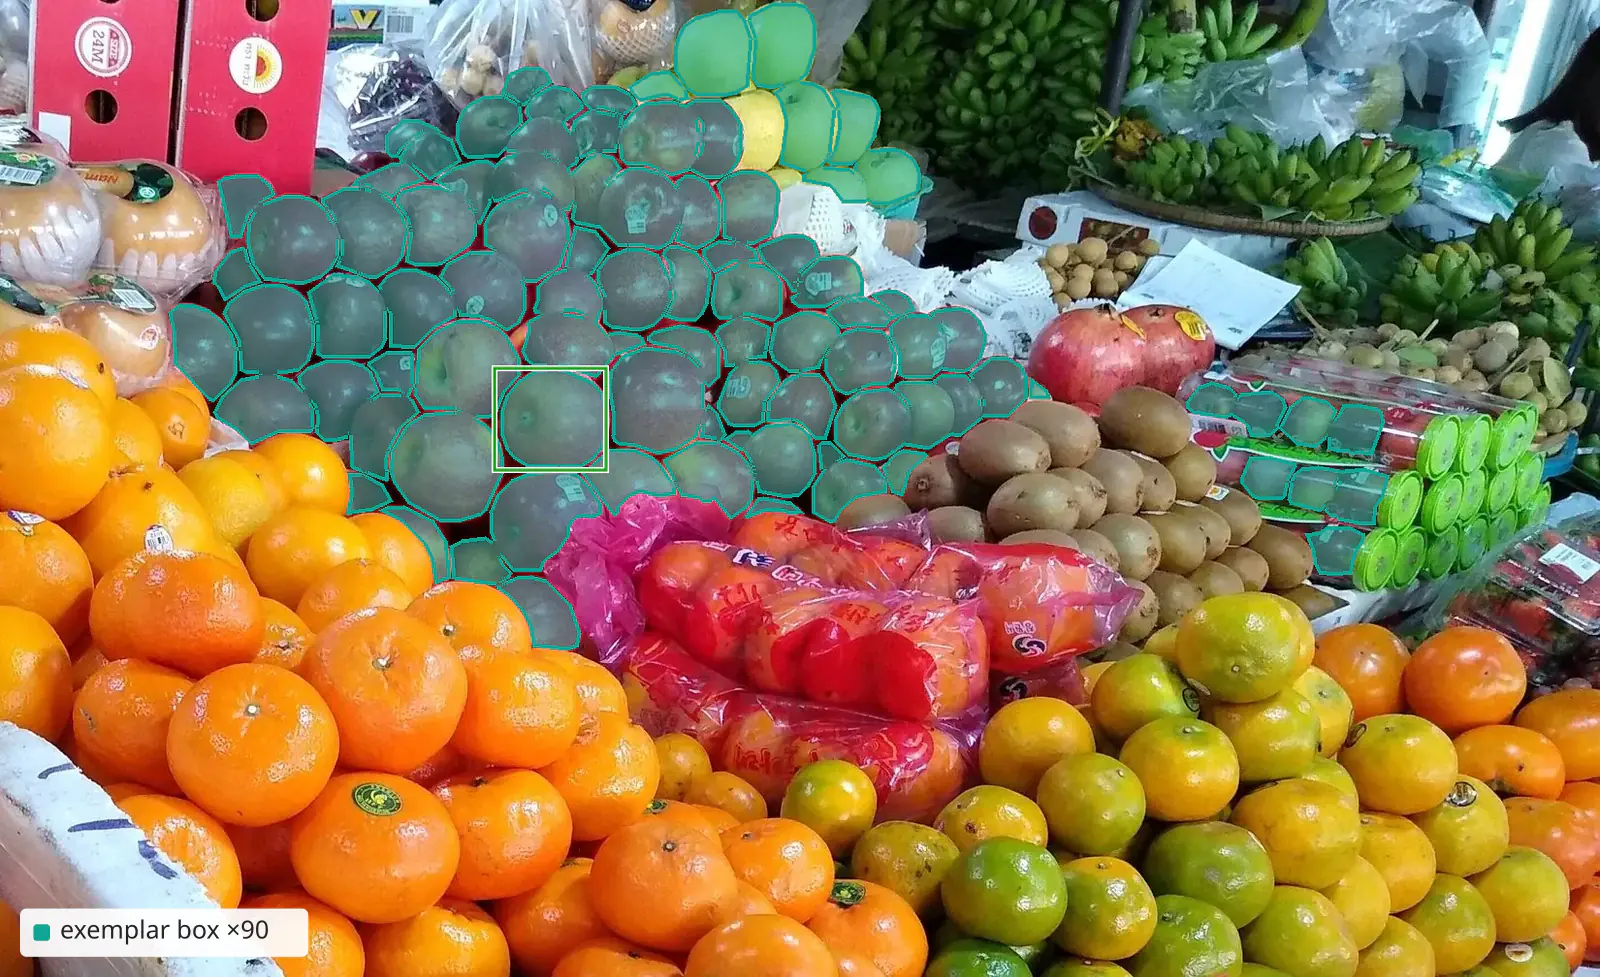
sam3: recorded Playground result for a single exemplar box (green outline). The 90 masks have the label _exemplar.
positive defaults to true, which means “find more like this”. With "positive": false the box is a negative exemplar (“not like this”): objects that look like the boxed one are left out. Negative boxes refine the query of each text prompt, or the box-only query. A box-only call needs at least one positive box, and a call whose boxes are all negative needs a text prompt. Points do not count: negative boxes next to points alone are not accepted. At most 10 exemplar boxes are accepted.
Mix with point prompts
Section titled “Mix with point prompts”A call can also carry point prompts. Each point returns exactly one object, the best mask under the point, and its instance has no label. Points are not affected by filter, nms, options.maxInstances or exemplar boxes. For the point walkthrough, see Mark objects with points.
Filter, limit and merge
Section titled “Filter, limit and merge”Instances below filter.minScore (default 0.5) are dropped, and at most options.maxInstances (default 100) search instances are returned. Size and area filters, overlap removal (nms), fragment cleanup and merging by group are options too, set for the whole call in options.defaults or for one prompt in prompts[].options. dropStats reports what each prompt lost. All options, their order and the limits: Post-processing.
Supported models
Section titled “Supported models”Concept prompts are served by sam3 only; sam-lite accepts neither text prompts nor exemplar boxes.
sam3 |
|
|---|---|
| Model | SAM 3 |
| Accepts | Text prompts (1 to 200 characters), exemplar boxes (positive or negative), points |
| Returns | One instance per match, labelled with the prompt or _exemplar |
| List price (credits) | 0.5 per image encoding + 0.05 per text prompt (exemplar boxes add no charge; a box-only call is one prompt), 0.02 per point |
| Pool | Paid: billed from the balance |
| Recorded processing time | About 390 to 560 ms (recorded concept-prompt calls) |
For how sam3 produces these results, see How it works.
Example call
Section titled “Example call”The text prompts car and person on the street scene of the first figure, sent to POST /v1/segment:
curl https://api.stack.foldbun.com/v1/segment \ -H "Authorization: Bearer $FOLDBUN_API_KEY" \ -H "Content-Type: application/json" \ -d '{ "model": "sam3", "image": { "id": "img_312c4e3a0ef23fa991baec515316f6b5897d4d534ad7058c57d8563cfcbdc6e2" }, "prompts": [{ "text": "car" }, { "text": "person" }] }'The response is abridged: the instance list and the polygon ring are shortened.
{ "id": "call_01a1913c-25a0-73fd-a074-7a6ac6154590", "model": "sam3", "image": { "id": "img_312c4e3a0ef23fa991baec515316f6b5897d4d534ad7058c57d8563cfcbdc6e2", "width": 1343, "height": 1008, "bytes": 388375, "contentType": "image/jpeg" }, "instances": [ { "prompt": 0, "label": "car", "score": 0.9696, "bbox": [0, 716, 207, 889], "area": 14261, "polygon": [ { "outer": [0, 888, 0, 762, 41, 744, 96, 718, 158, 724, 206, 781, 206, 888] } ] } ], "cache": "miss", "imageFee": 0.5, "cost": 0.6, "balance": 998.4, "timing": { "queueMs": 0, "processingMs": 473 }, "billing": { "lines": [ { "unit": "encode_image", "quantity": 1, "unitPrice": 0.5, "amount": 0.5, "waived": false }, { "unit": "prompt", "quantity": 2, "unitPrice": 0.05, "amount": 0.1, "waived": false } ], "total": 0.6, "charged": true, "pool": null }}Reading the response
Section titled “Reading the response”instancesholds one entry per match: 9 cars and 18 people in the figure, of which the JSON shows the first.promptis the index intoprompts(0 iscar) andlabelrepeats the prompt text; instances from exemplar boxes carry the label_exemplar.score0.9696 is the detection confidence of the instance, from 0 to 1.bboxandpolygonare in pixels of the oriented original, 1343 × 1008 here (image.width,image.height).bboxis[x1, y1, x2, y2]with x2 and y2 exclusive, andareais the pixel area of the object.polygonis a list of parts, largest first: each has anouterring and, if the object has holes,holes, all flat integer arrays[x0, y0, x1, y1, ...]. A pixel mask is returned only on request (see Post-processing and Images).dropStats, not shown here, lists for each prompt how many candidates were dropped and why. It is empty when nothing was dropped.cacheismissandimageFeeis 0.5: the image was encoded in this call. A later call on the same image, for example a point refinement, normally returnshitwithimageFee0.billing.linesshowsencode_imageonce andpromptwithquantity2, one per text prompt.chargedistrueandpoolisnull, socostis thetotaland was debited frombalance.
All fields: API reference.
Cost of this call. 0.5 (encode_image) + 2 × 0.05 (prompt) = 0.60 credits on a new image, as charged in this response; 0.10 credits when the encoding is cached. Unit prices: Billing.
Endpoints and reference
Section titled “Endpoints and reference”| Endpoint | In this use case | Reference |
|---|---|---|
POST /v1/segment |
Every instance of a concept from 1 to 50 prompts: text prompts, exemplar boxes and optionally points | API reference |
sam3: how the model works, its limits and measured latency.- How SAM calls are billed: units and worked examples, including prompts with exemplar boxes.
- Interactive segmentation: single objects from points, boxes and clicks, with
sam3orsam-lite.