Text and documents
PaddleOCR-VLpaddleocr-vl
Document parsing: layout, tables and formulas to Markdown.
2 per page
Paid

 Foldbun Stack
PP-OCRv6 reads text from screenshots, photos of labels and image regions, and returns text lines with confidence, line boxes and word boxes.
| Billed item | Unit | Credits |
|---|---|---|
| Text recognition One image per request. | per image | 0.25 ≈ US$0.00025 top-up |
Included in the public pool: 100 calls per day after sign-up. Prices are in credits. Failed calls cost nothing.
Recorded responses of the API on sample images.
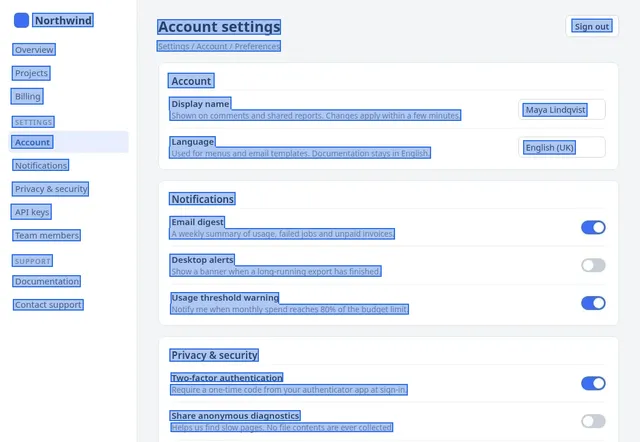
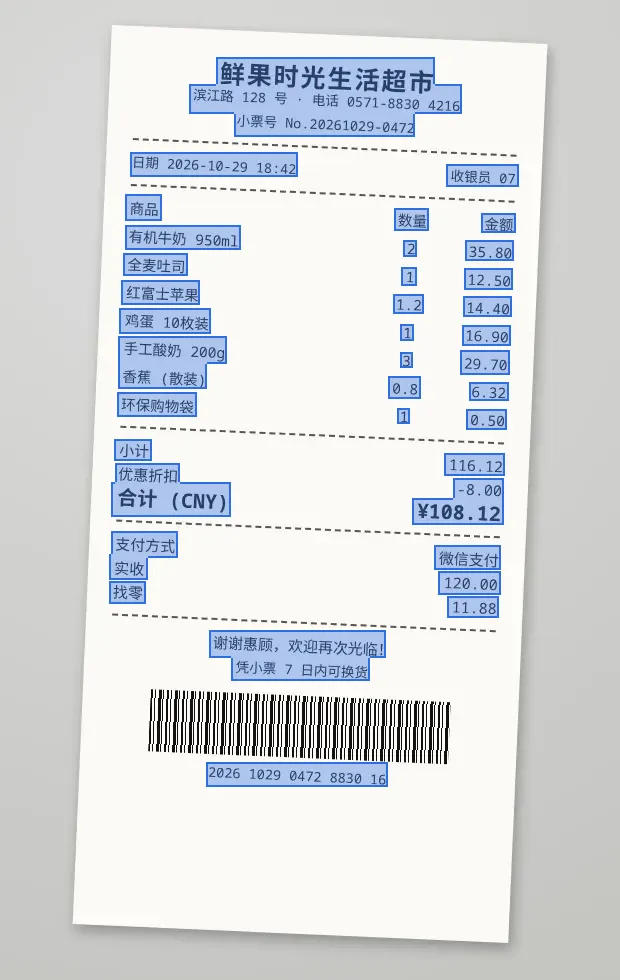
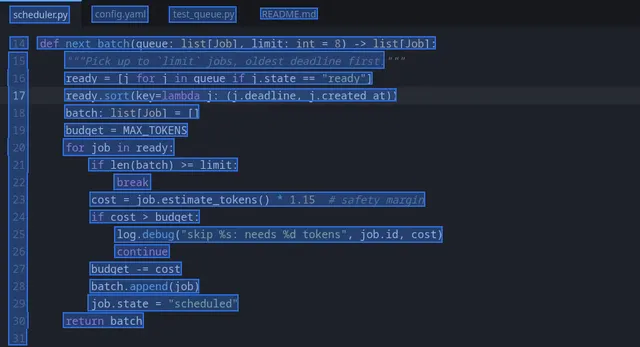
POST https://api.stack.foldbun.com/v1/ocr with a Bearer API key.
# macOS: replace "base64 -w0 settings.webp" with "base64 -i settings.webp"
curl https://api.stack.foldbun.com/v1/ocr \
  -H "Authorization: Bearer $FOLDBUN_API_KEY" \
  -H "Content-Type: application/json" \
  -d @- <<EOF
{"model": "ppocr-v6", "image": {"base64": "$(base64 -w0 settings.webp)"}}
EOF
import base64, os, requests

with open("settings.webp", "rb") as f:
    image = base64.b64encode(f.read()).decode()

r = requests.post(
    "https://api.stack.foldbun.com/v1/ocr",
    headers={"Authorization": f"Bearer {os.environ['FOLDBUN_API_KEY']}"},
    json={"model": "ppocr-v6",
          "image": {"base64": image}},
    timeout=60,
)
r.raise_for_status()
print(r.json())
{
  "id": "call_01a1913d-55cd-7bee-ba86-bbbef2aa9bae",
  "model": "ppocr-v6",
  "image": {"height": 760, "id": "img_2dedd071…22e6", "width": 1100},
  "lines": [
    {
      "text": "Northwind",
      "confidence": 1,
      "bbox": [55, 22, 161, 47],
      "quad": [
        [55, 22],
        [161, 22],
        [161, 47],
        [55, 47]
      ],
      "words": [
        {
          "text": "Northwind",
          "confidence": 1,
          "bbox": [67, 22, 154, 47],
          "quad": [
            [67, 22],
            [154, 22],
            [154, 47],
            [67, 47]
          ]
        }
      ]
    }
    … 34 more
  ],
  "cost": 0.25,
  "balance": 1234.31
}| Field | Description |
|---|---|
| image | {"base64": "…"} or {"id": "img_…"} from an earlier response. |
| options.minConfidence | Drop lines below this confidence, 0–1, default 0.5. |
| options.words | Include word-level boxes, default true. |
| Call | Credits |
|---|---|
| 1 image 0.25 | 0.25 ≈ US$0.00025 top-up |
| 1,000 images 1,000 × 0.25 | 250 ≈ US$0.25 top-up |
GET /v1/modelsEach image costs 0.25 credits, whatever the number of lines. The model is in the public pool: 100 calls per day at no charge after sign-up. Failed calls cost nothing.
ppocr-v6 reads text lines from screenshots and image regions and costs less. paddleocr-vl parses a whole document page into ordered blocks, tables and formulas and returns Markdown, at 2.0 credits per page.
Yes, by default. Each line carries its text, confidence, box, quadrilateral and word boxes. Set options.words to false to omit the word boxes.
Call PP-OCRv6 through the REST API; the docs list request and response formats.